전체 글 213

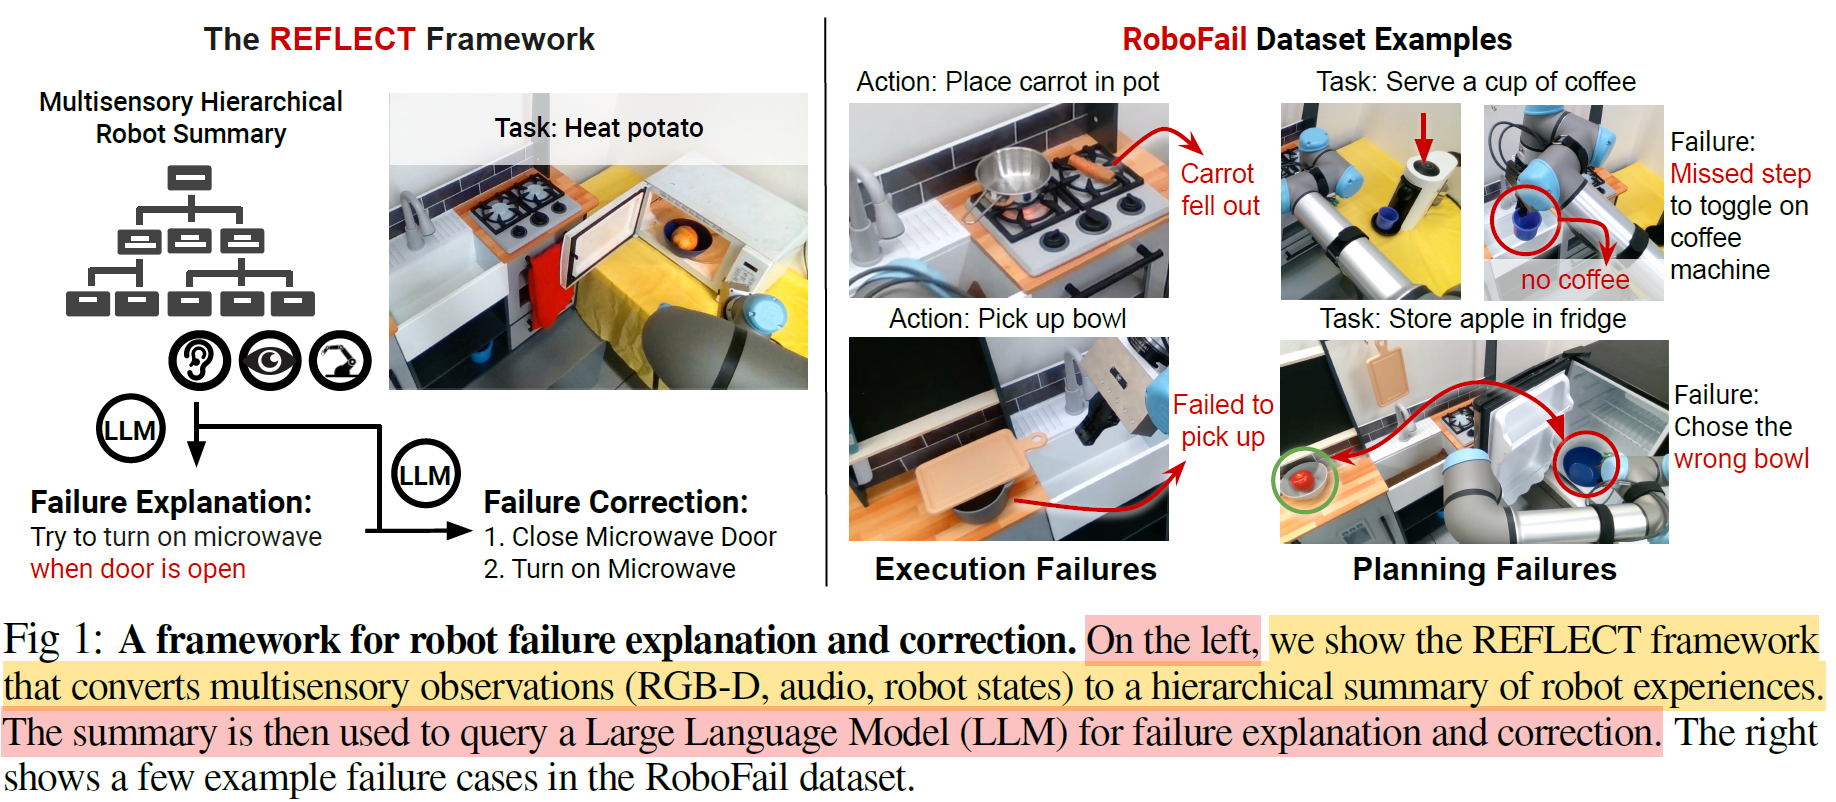
REFLECT: Summarizing Robot Experiences for FaiLure Explanation and CorrecTion

AbstractRecently, Large Language Models (LLMs) have been demonstrated strong reasoning abilities on textual input.To leverage the power of LLMs for robot failure explanation, this paper *introduces REFLECT, a framework *which queries an LLM to reason about failures based on a hierachical summary of the robot's past experiences generated from multisensory observation.This paper demonstrate that t..
Physical AI 2026.11.11

Inference-time Physics Alignment of Video Generative Modelswith Latent World Models

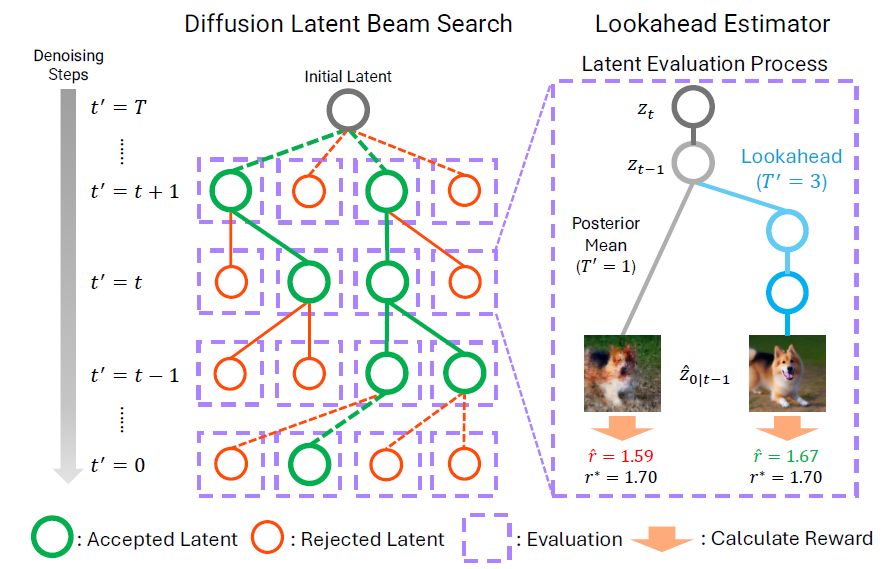
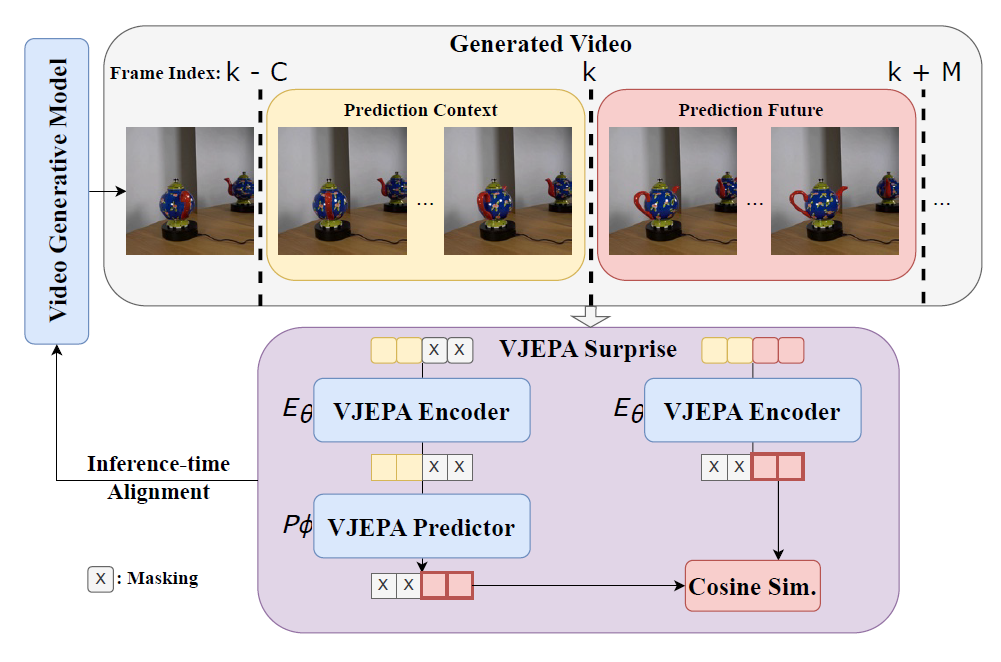
AbstractVideo generation의 physics plausibility 개선 문제를 inference-time alignment로 다룬다특히 latent world model의 physics prior를 이용1. Introduction2. Methodology: WMReward2.2. Steering for Better Physics Plausibility$$p^{*}(x) \propto w(x)p(x),$$$p(x)$는 pre-trained video model distribution$w(x)$는 reward $r(x)$로부터 구축된 weighting function2.3. Latent World Model Reward Signal본 논문에서는 VJEPA를 Reward model로 바꾸기 ..

Text-to-video 2026.08.10

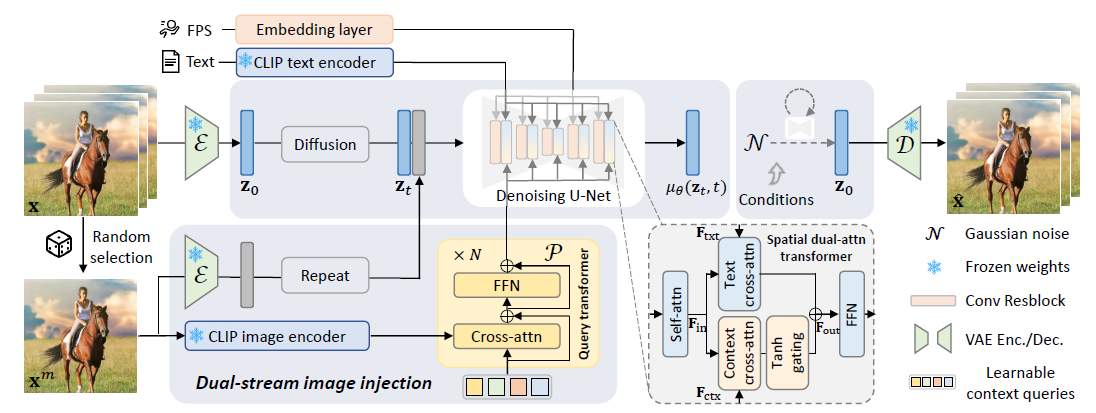
DynamiCrafter: Animating Open-domain Images with Video Diffusion Priors

Abstract.정지 이미지에 애니메이션 효과를 추가하는 것은 매력적인 visual experience를 제공본 논문에서는 open-domain images에 대한 dynamic content의 생성을 탐구한다핵심 아이디어는, test-to-video diffusion model의 motion prior를 이용하여 image를 생성 과정에 통합하는 것주어진 이미지를 Query Transformer를 이용하여 text-aligned rich image context representation로 project한다그리고 좀 더 정확한 이미지 정보를 보충하기 위해서, full image를 initial noise에 concatenating한다1 Introduction최근에 text-to-video(T2V) ge..

Text-to-video 2026.01.12

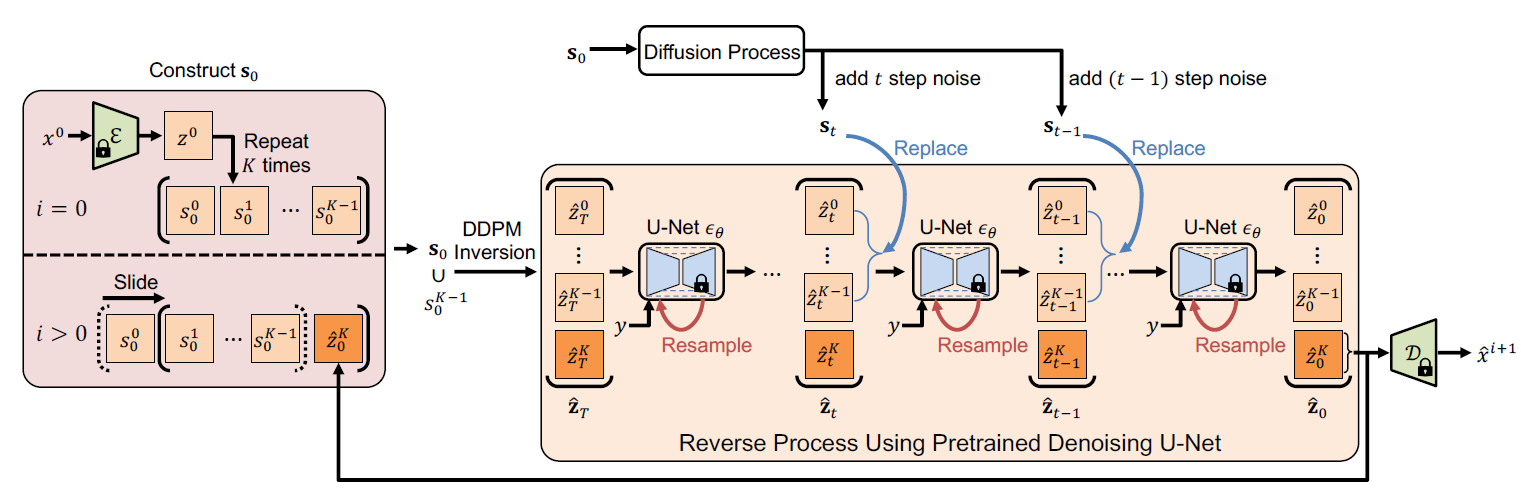
TI2V-Zero: Zero-Shot Image Conditioning for Text-to-Video Diffusion Models

AbstractText-conditioned image-to-video generation (TI2V)는 주어진 image와 text description으로 시작하여 realistic video를 생성하는 것이 목표기존 TI2V framework는video-text dataset으로 costly training과text and image conditioning을 위한 specific model design이 필요했다이 논문에서는 zero-shot, tuning-free method인 TI2V-zero를 제안한다어떠한 optimization, fine-tuning, exteral module 없이pre-trained text-to-video(TI2V) diffusion model에 제공된 이미지에 따라 ..

Text-to-video 2026.01.10

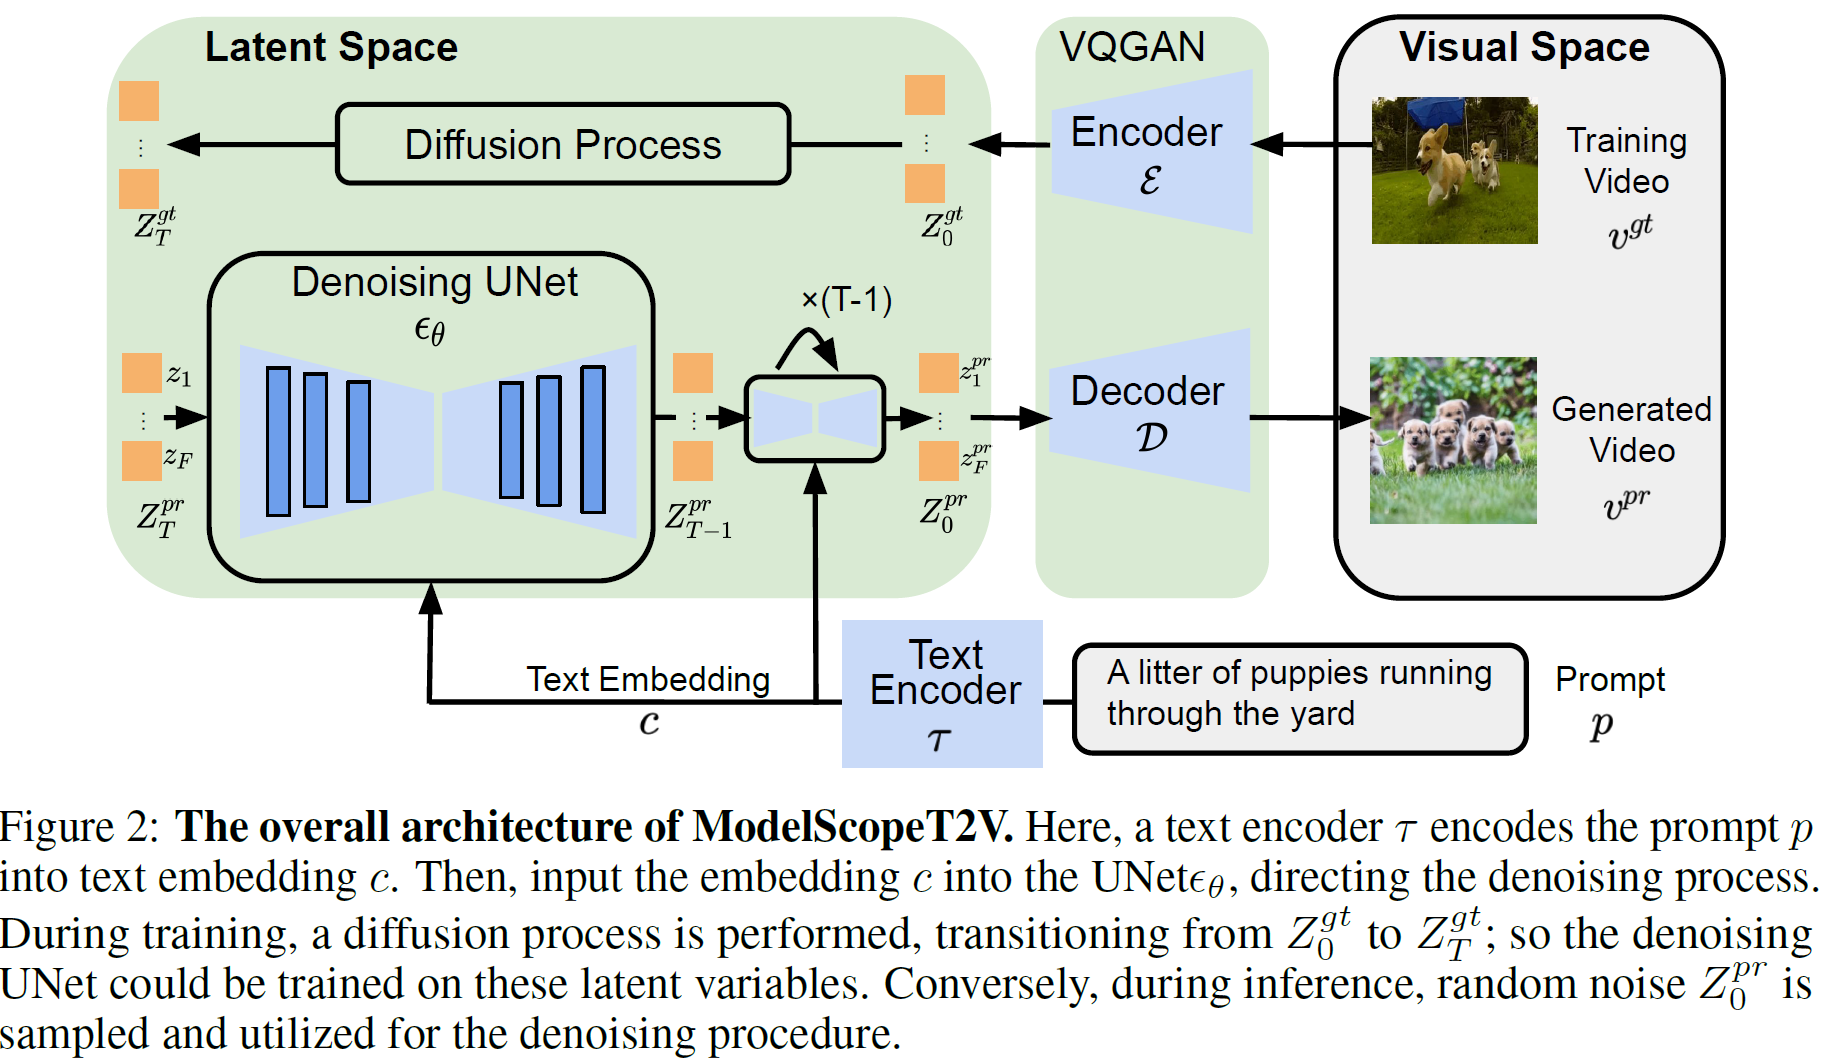
ModelScope Text-to-Video Technical Report

AbstarctModelScopeT2V는 spatio-temporal block을 통합하여 consistent frame을 생성하고 smooth motion 전환을 보장모델은 프레임 수가 변하더라도 적응할 수 있도록, image-text and video-text에 적합ModelScopeT2V는 VQGAN, text encoder, denoising UNet을 함께 사용1 IntroductionVideo 생성의 주요 문제는 sub-optimal fidelity and modtion discontinuity에 있다ModelScopeT2V는 비디오 생성을 위한 trainable baseline을 제안ModelScopeT2V는 Stable Diffusion model의 spatial part를 초기화하여 Sp..

Text-to-video 2025.12.17